Thesis/Dissertation: Jakub Neruda, učo 524944: Python Libraries for Storing Embeddings on Disk
Bachelor's thesis
Python Libraries for Storing Embeddings on Disk
Abstract
Tato bakalářská práce se zabývá ukládáním velkých matic vektorových embeddingů na disk pomocí knihoven dostupných v jazyce Python. Práce porovnává poleově orientované formáty, sloupcová datová úložiště a vestavěné databáze z hlediska výkonu při typických operacích, jako je sekvenční a náhodný přístup, vyhledávání podle identifikátoru, změny dat a škálování s velikostí datasetu. Hodnocení je založeno …more
Abstract
This bachelor’s thesis investigates on-disk storage of large vector embedding matrices using Python-accessible libraries. It compares array-oriented formats, columnar storage, and embedded databases with respect to performance under common operations, including sequential and random access, identifier-based lookup, dataset mutations, and scalability. The evaluation is based on a unified benchmarking …more
Thesis description
The student will describe, compare, and evaluate the capabilities and performance of Python libraries for manipulating and storing dense vector embeddings on disk. Specifically, the student will compare the NumPy, Pandas, h5py, PyTables, PyArrow, and SQLite libraries and their underlying formats, including Pickle, NPY, CSV, HDF5, Zarr, Apache Parquet, and Apache Arrow. Each library will be described in terms of at least the following features: the ability to efficiently retrieve an embedding based on its user-specified identifier, support for metadata and its indexing for efficient filtering, and iterative or chunk-based data access. Format properties such as data orientation and compression support will also be discussed.
A performance evaluation of each library will be conducted through a series of benchmarks, including inserting single and bulk embeddings, removing single and bulk embeddings, reading embeddings by their position and embedding identifier, reading multiple embeddings stored both consecutively and randomly across the dataset, appending new embeddings, and serializing and deserializing the entire dataset. In addition, the student will explore and experimentally evaluate selected file compression techniques to reduce the overall size of serialized embeddings on disk. The performance tests will be evaluated using a combination of HDD and SSD storage on a subset of embeddings from the LAION-5B image collection and the DEEP1B dataset from ANN-Benchmarks.
22/12/2025 08:31, RNDr. David Procházka, UČO 485104
 English
Consultant
Theses on a related topic
List of theses with an identical keyword.
-
Python Libraries for Storing Embeddings on Disk
Bc. Jakub Neruda, UČO 524944 -
AI Image Analysis Pipeline Implementation for Digital Pathology
Mgr. Andrej Kubanda -
Classification of Threat Intelligence via Machine Learning Methods
Bc. Martin Šoltisík -
Poker game with AI opponents
Ing. Richard Plesník -
Classification of Threat Intelligence via Machine Learning Methods
Bc. Martin Šoltisík -
Research of Fedora Status for Machine Learning
Mgr. Dominik Tuchyňa -
Product package generator using GAN
Ing. Jakub Oršula, UČO 485199 -
Time Series Analysis in Network Traffic Monitoring
Bc. Štěpán Trčka
Folders
Files
-
Přidání souboru
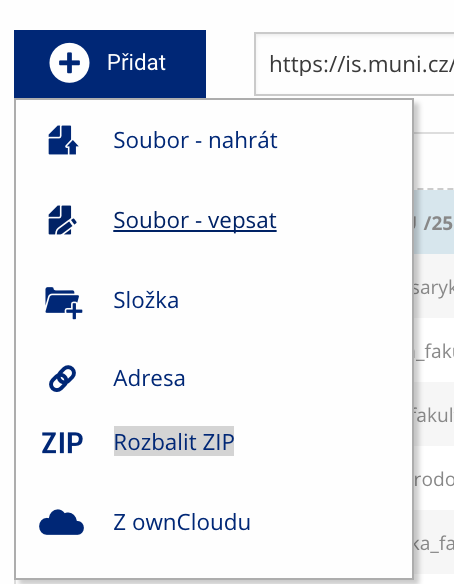 Soubor nebo složku lze nahrát pomocí tlačítka Přidat.
-
Další operace se soubory
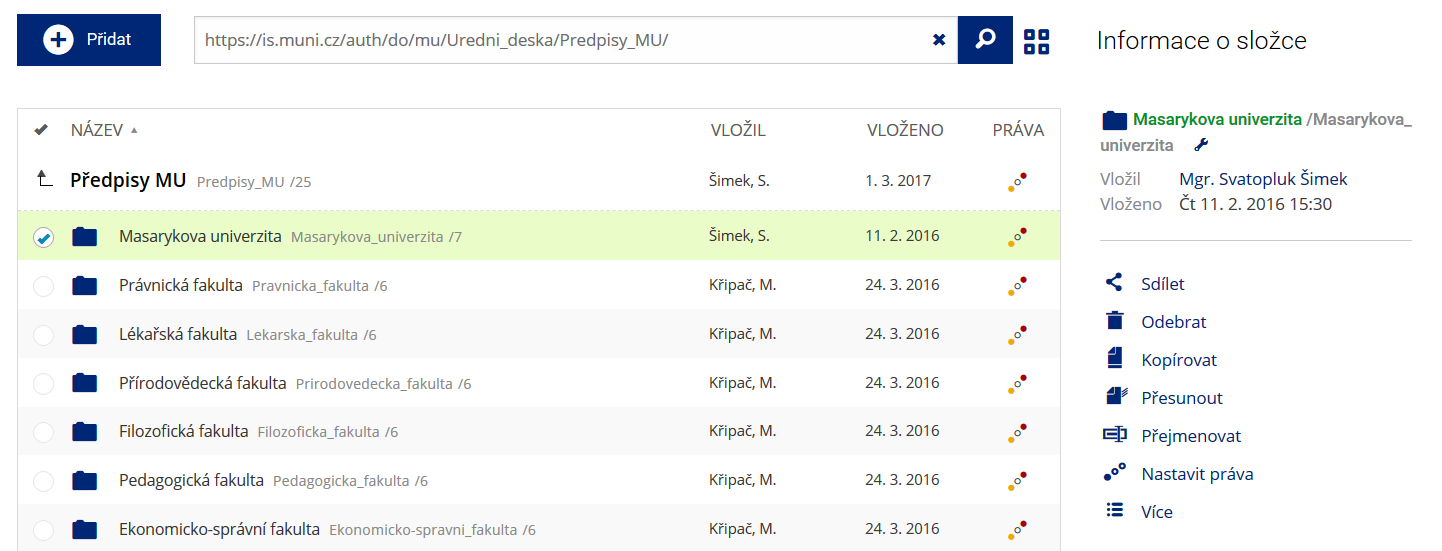 Podrobnosti lze zjistit označením příslušného řádku.
-
Pohled pro experty
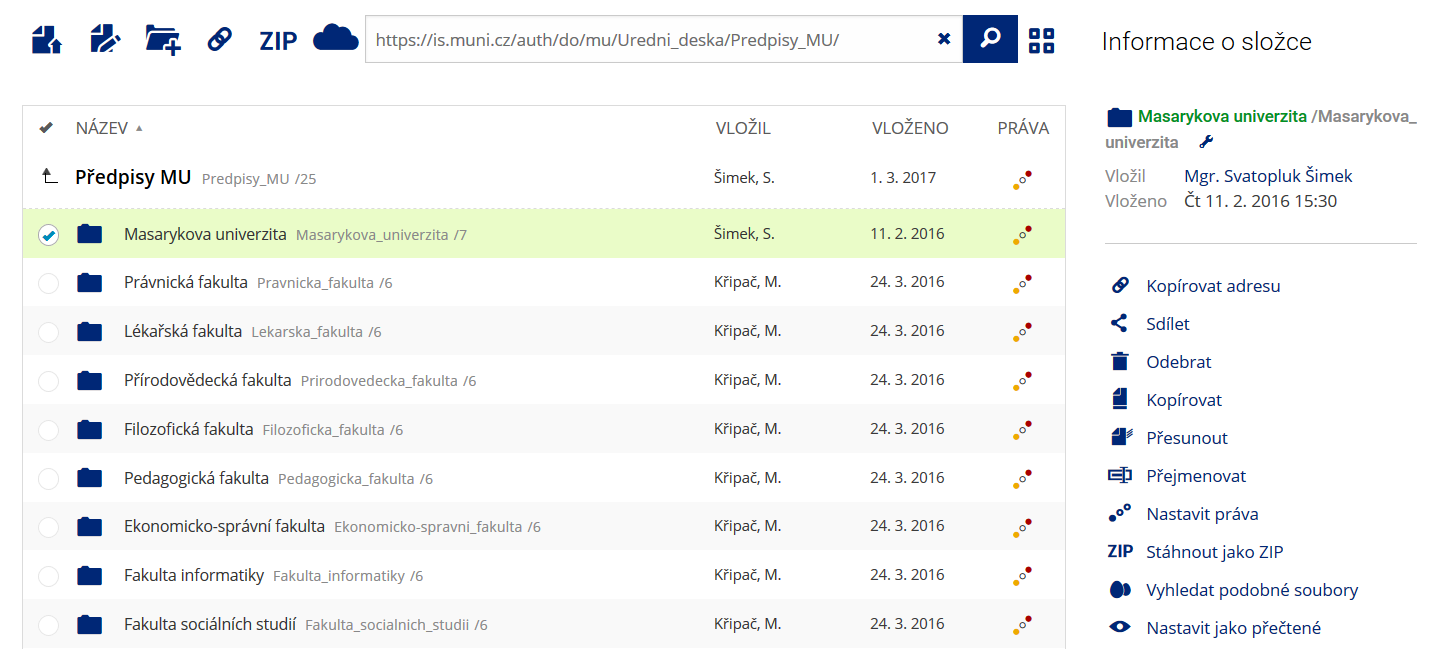 Pro častou práci je možné zvolit režim Více možností.
-
Vyhledávání souborů
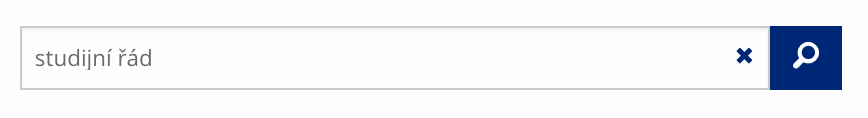 Vyhledávaný výraz můžete zadat přímo do adresního řádku.
-
Rychlý přístup k souborům
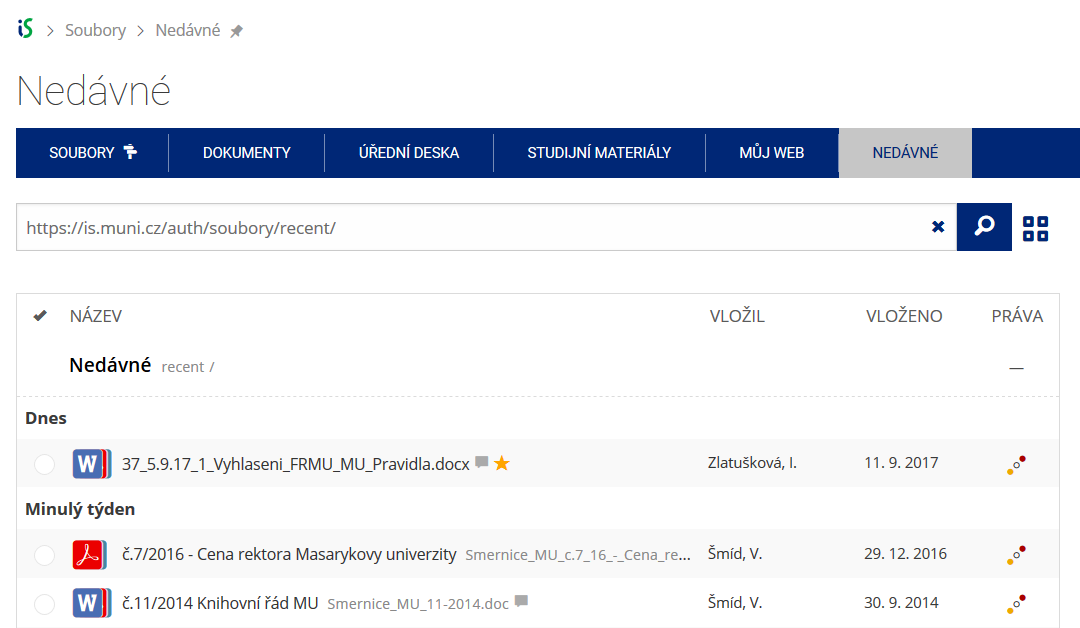 Pomocí funkce Nedávné je možné se rychle vrátit k právě prohlíženým souborům. Oblíbené soubory je také možné označit Hvězdičkou.